Microsoft Expands Hybrid Intelligence on Windows With Local Models, HydraFusion & llama.cpp


 2 min. read
 Published on
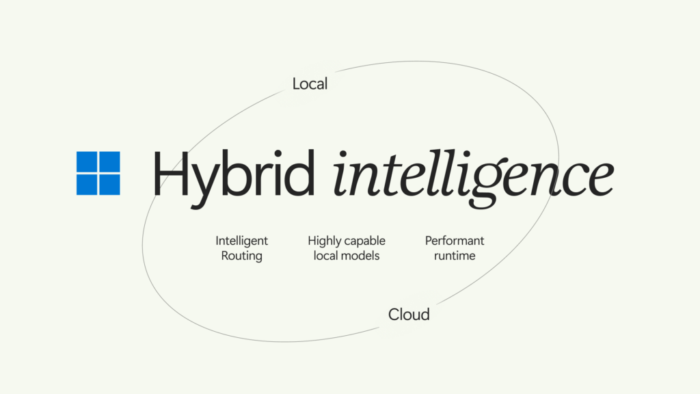
Microsoft is expanding its hybrid intelligence strategy for Windows, combining local AI models with cloud-based intelligence to deliver more capable AI experiences while reducing reliance on cloud compute.
Frontier AI models are coming to Windows PCs
The company says growing AI models are putting pressure on cloud budgets, making it increasingly important to run capable models locally. Microsoft is now bringing MAI Code 1.1 Flash to devices, using 3-bit precision to cut the model size by nearly 80% while maintaining coding quality and supporting a 256K context window locally.
Microsoft is also working with NVIDIA to bring an upcoming Nemotron model with more than 70 billion parameters, quantized to 2-bit precision so it can use just over 20GB of memory. DeepSeek V4 Flash, a 284-billion-parameter model, is also being positioned for local operation on RTX Spark-powered hardware.
The idea is to let local models handle tasks directly on the PC, while cloud models remain available when more intelligence or compute is required.
GitHub HydraFusion gets local AI support
Microsoft is also extending GitHub HydraFusion to Windows. The system can route tasks between different AI models, and it will now be able to use models running locally on the device instead of relying exclusively on cloud models. Hybrid intelligence powered by HydraFusion is coming to the GitHub Copilot app, GitHub Copilot CLI and Visual Studio Code in experimental preview later this month.
Microsoft is also expanding the software foundation behind local AI. Windows ML, its runtime for deploying models across GPUs, NPUs and CPUs, is gaining llama.cpp support, giving developers easier access to open-source models and newer AI releases.

Read our disclosure page to find out how can you help Windows Report sustain the editorial team. Read more


Improve this guide
User forum
0 messages