OpenAI Launches GPT-6.1 Sol with Near-Astra Performance at One-Fifth the Price


 2 min. read
 Published on
OpenAI has launched GPT-6.1 Sol, an upgraded version of GPT-6 Sol that targets coding, computer use and professional workflows while costing just one-fifth of GPT-6 Astra at standard token rates. The company says the new model gets close to Astra on several demanding evaluations while significantly improving on the previous Sol model.
GPT-6.1 Sol delivers a major performance jump
GPT-6.1 Sol costs $2 per million input tokens and $10 per million output tokens, compared with $10 and $50 for GPT-6 Astra. Cached input is priced at just $0.10 per million tokens, which OpenAI says is 95% cheaper than standard input and 50% cheaper than GPT-6 Sol’s cached input pricing.
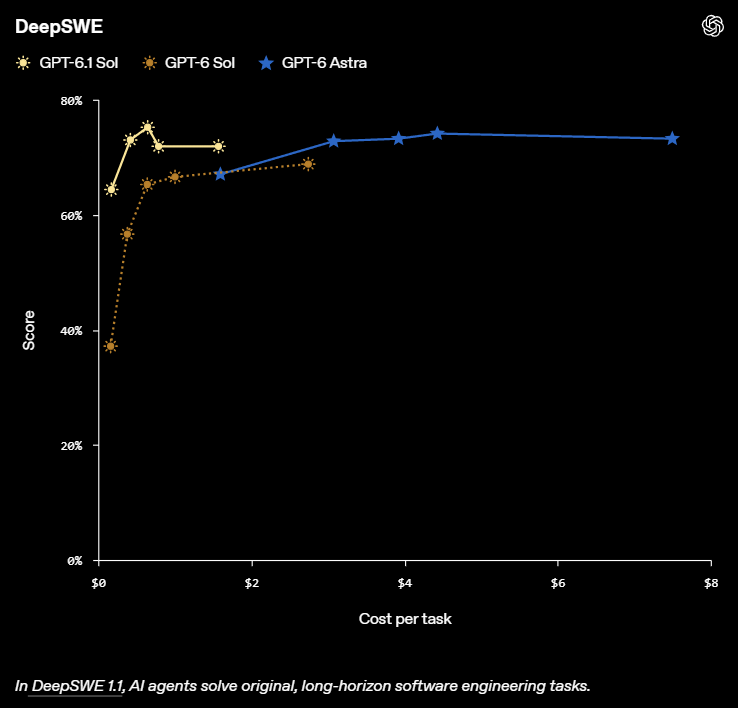
On the DeepSWE v1.1 coding benchmark, GPT-6.1 Sol matches GPT-6 Astra while scoring 6.4 percentage points higher than GPT-6 Sol at a lower reasoning effort and cost.
The model also shows performance gains in professional document work. OpenAI says GPT-6.1 Sol scores higher than Opus 5.5 with fallbacks on GDP.pdf while costing less than half as much per task. Computer use is another major focus of the latest model. On the offline set of OSWorld 2.0, GPT-6.1 Sol scores seven percentage points higher than GPT-6 Sol at maximum reasoning effort. It comes within 2.1 points of Astra while costing roughly one-seventh as much per task.
GPT-6.1 Sol also targets scientific and factual work
OpenAI says GPT-6.1 Sol more than doubles GPT-6 Sol’s score on Terminal-Bench Science 0.1 at maximum reasoning effort, while costing less than half as much per task. The model also reduces factual errors on difficult prompts. At low reasoning effort, its factual error rate falls from 11.4% with GPT-6 Sol to 7.7%, according to OpenAI’s testing.
Availability
GPT-6.1 Sol is available now to Plus, Pro, Business, Enterprise and Edu users in ChatGPT Work and Codex, while it is not yet available in regular Chat. Developers can access it through the API as gpt-6.1-sol. OpenAI also plans to bring Ultrafast to Codex, with token generation up to eight times faster than the standard speed.

Read our disclosure page to find out how can you help Windows Report sustain the editorial team. Read more


Improve this guide
User forum
0 messages